|
I am an Tenure-Track Associate Professor at the School of Mechanical Engineering, Hefei University of Technology. I received the Ph.D. degree in the Department of Automation at University of Science and Technology of China, advised by Prof. Zhen Kan. |

|
|
|
|
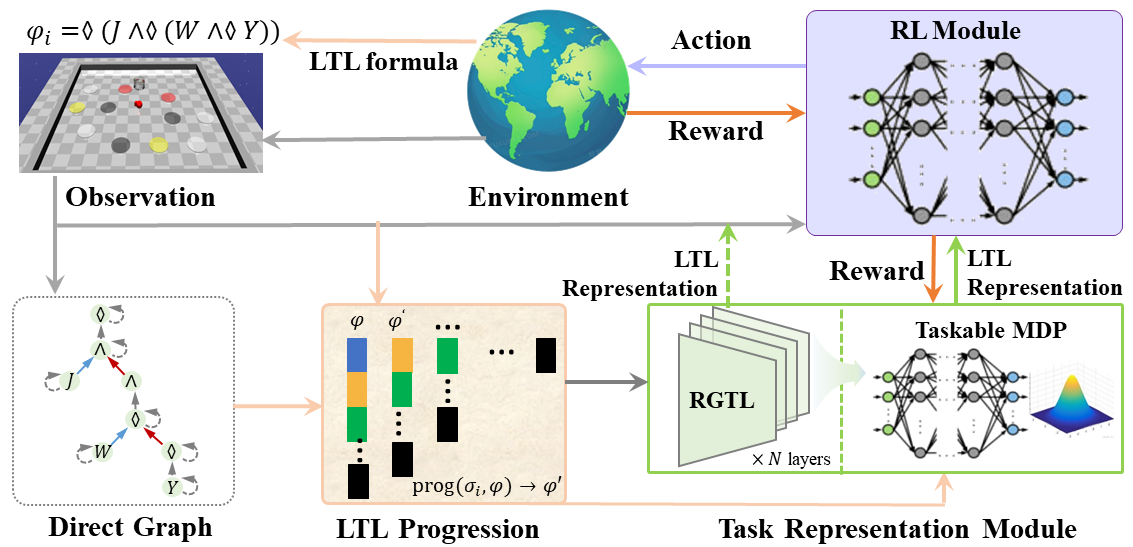
Paper / Website IEEE Transactions on Neural Networks and Learning Systems (Journal), 2026, Accepted We propose LOTUS, a temporal logic inspired universal task representation framework that can be seamlessly integrated into any RL algorithm to enhance agent performance across diverse task settings. |
|
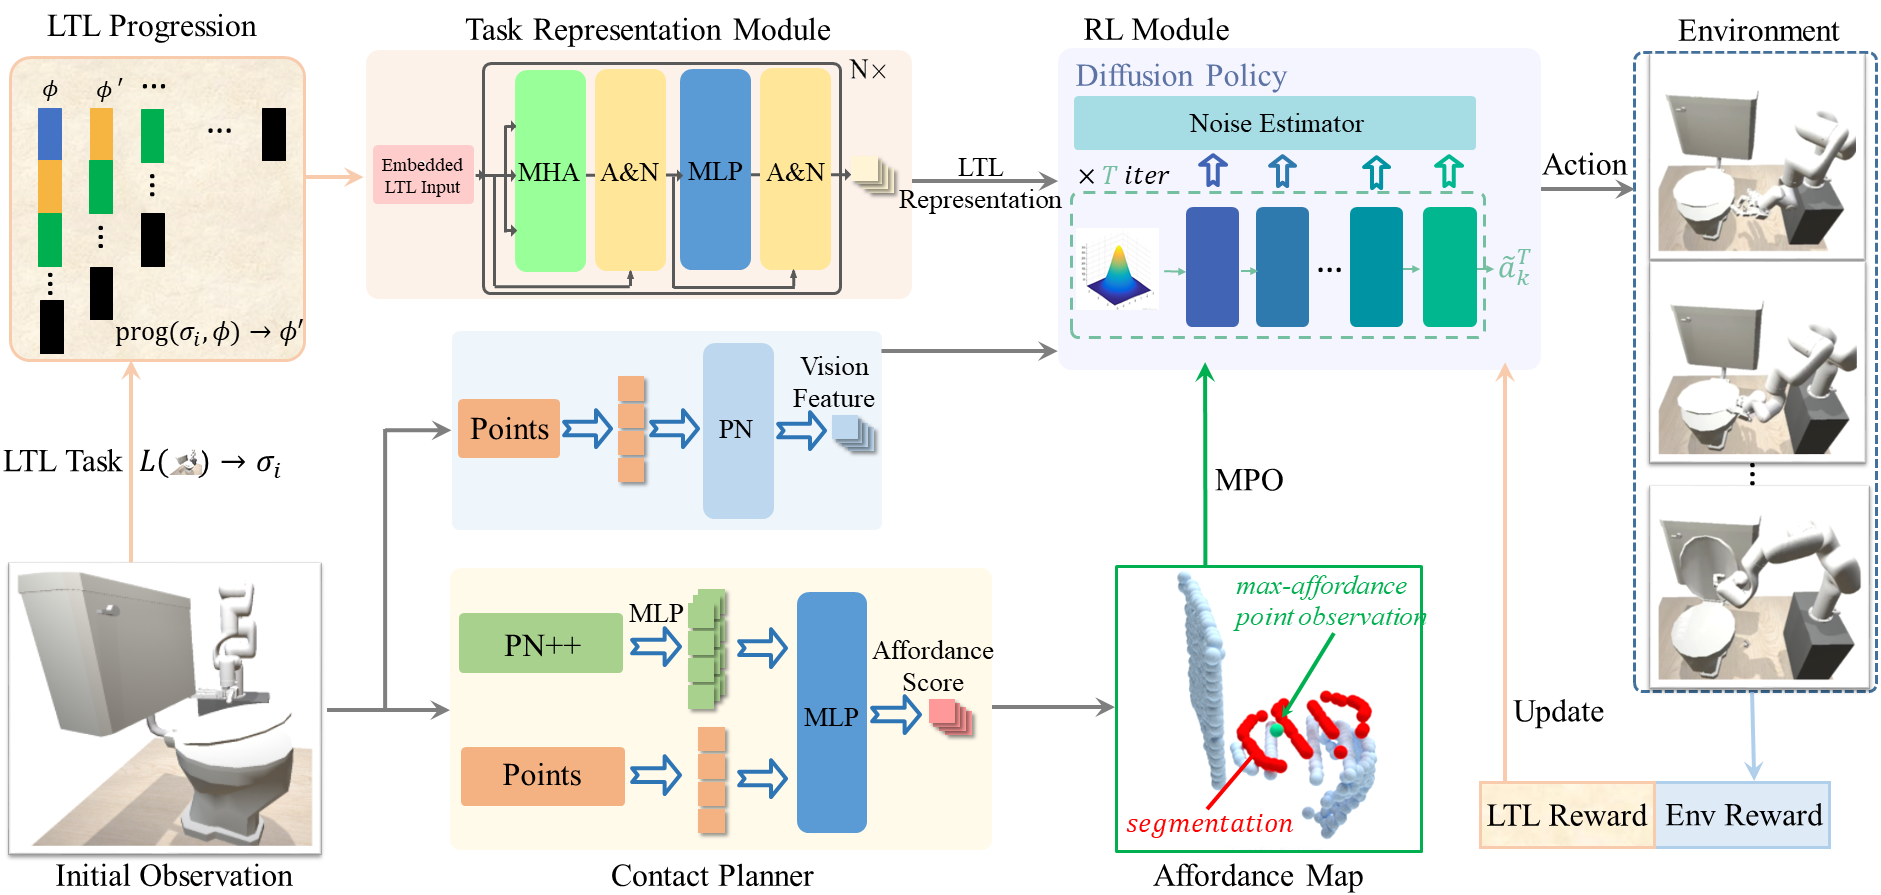
Paper / Website IEEE/ASME Transactions on Mechatronics (Journal), 2025, Accepted We introduce DART, a novel framework that enhances a diffusion-based policy with affordance learning and linear temporal logic representations to improve the learning efficiency and generalizability of articulated dexterous manipulation. |
|
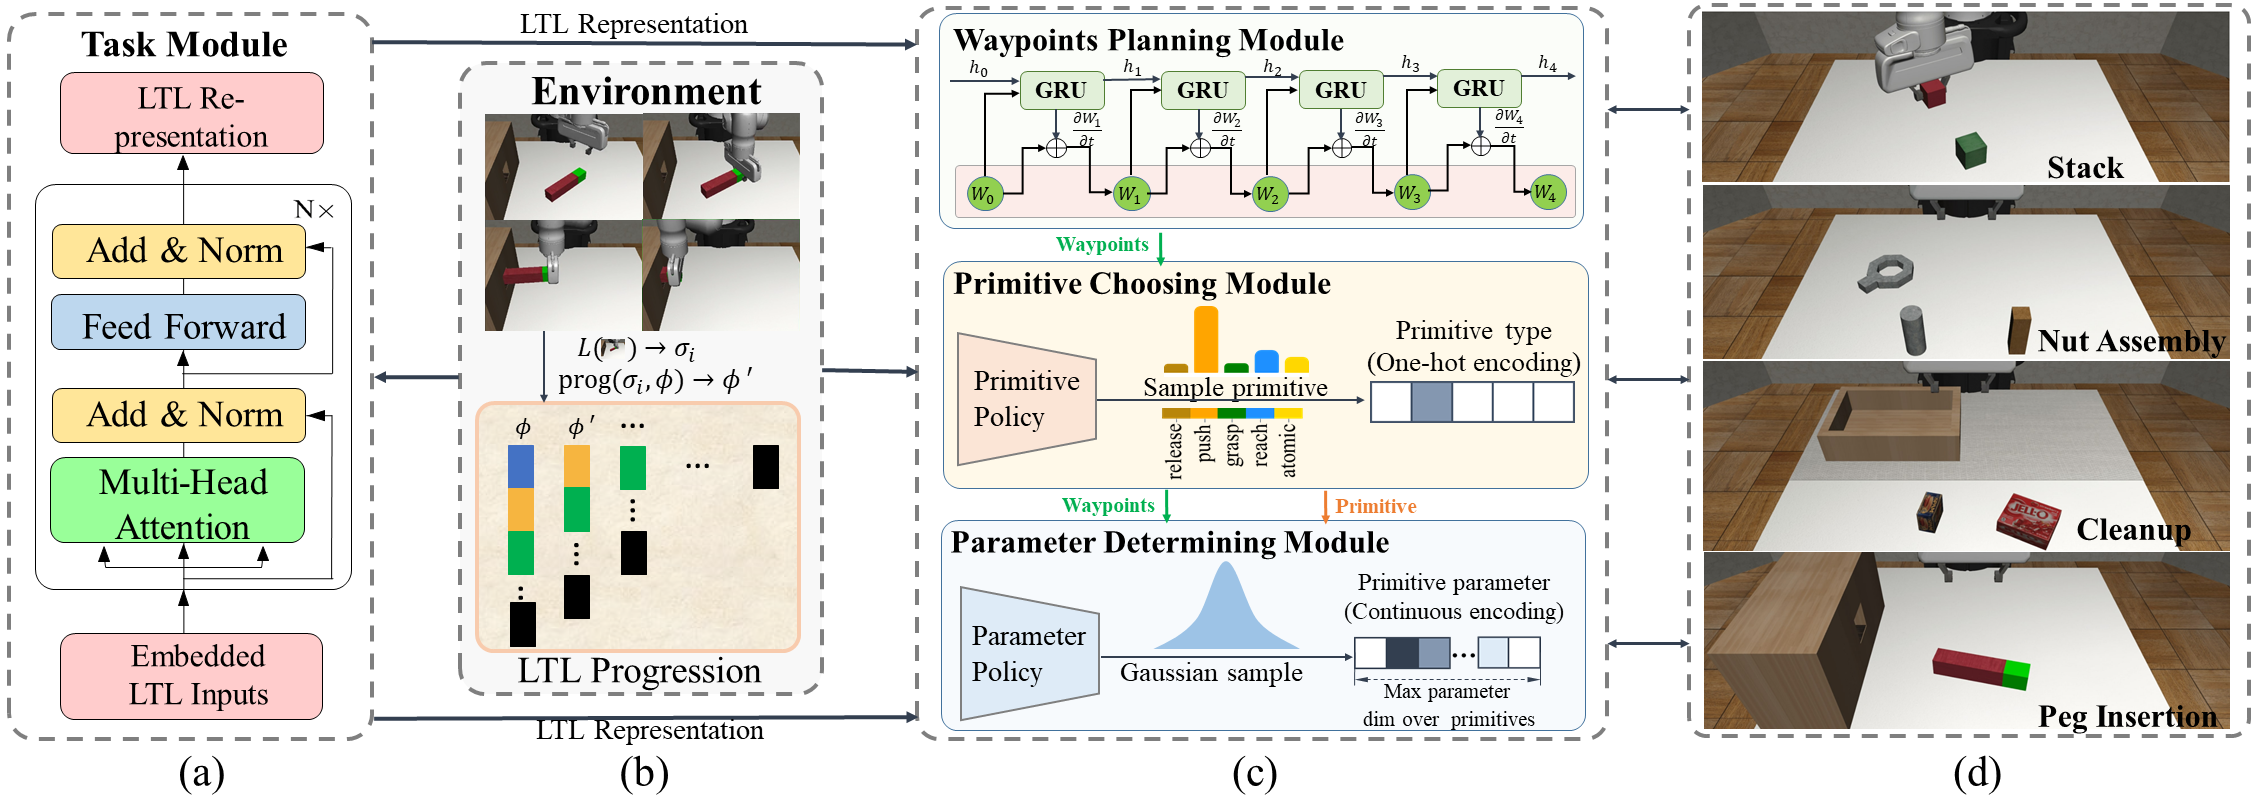
Paper / Website / Code IROS (Conference), 2024, Accepted We develop a Temporal-Logicguided Hybrid policy framework (HyTL) which exploits three-level decision layers to facilitate robot learning. |
|
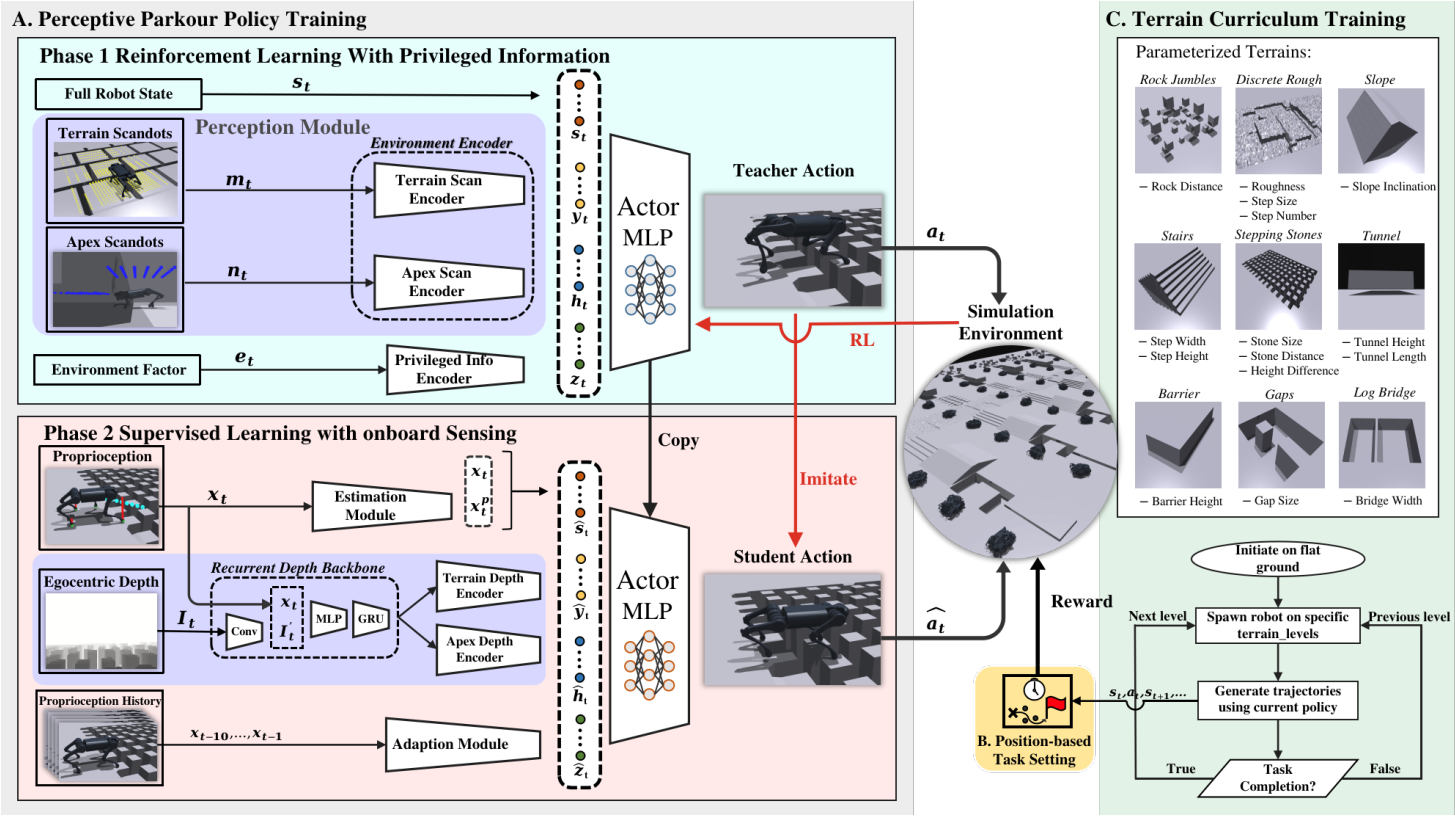
Paper / Website / Code IROS (Conference), 2024, Accepted We develop an End-to-End Legged Perceptive Parkour Skill Learning (LEEPS) framework to train quadruped robots to master parkour skills in complex environments. |
|
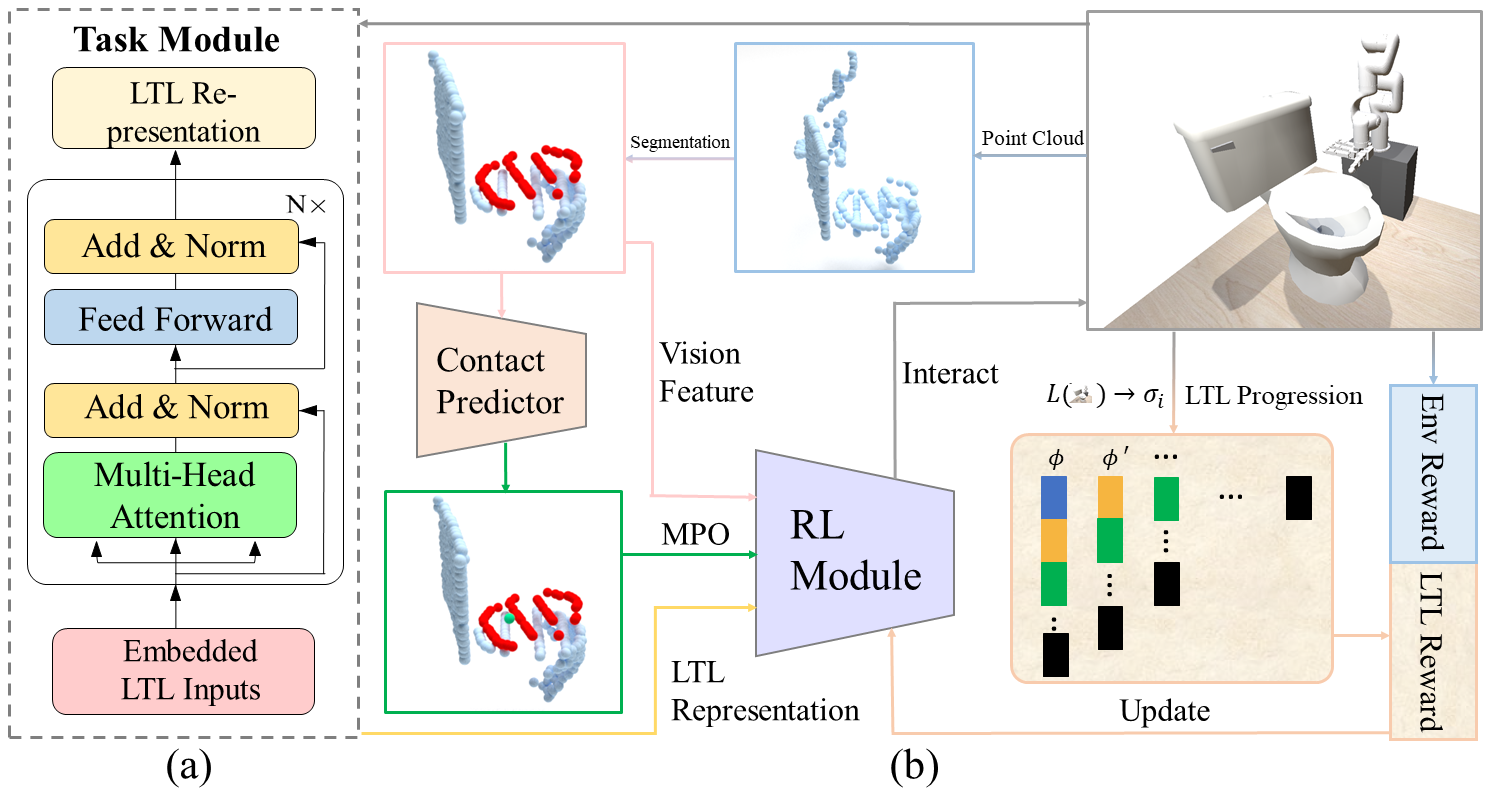
Paper / Website ICAIS&ISAS (Conference), 2024, Accepted We develop a temporal logic guided affordance learning framework for generalizable dexterous manipulations (TALD), which exploits affordance learning and task semantics to further improve generalization performance. |
|
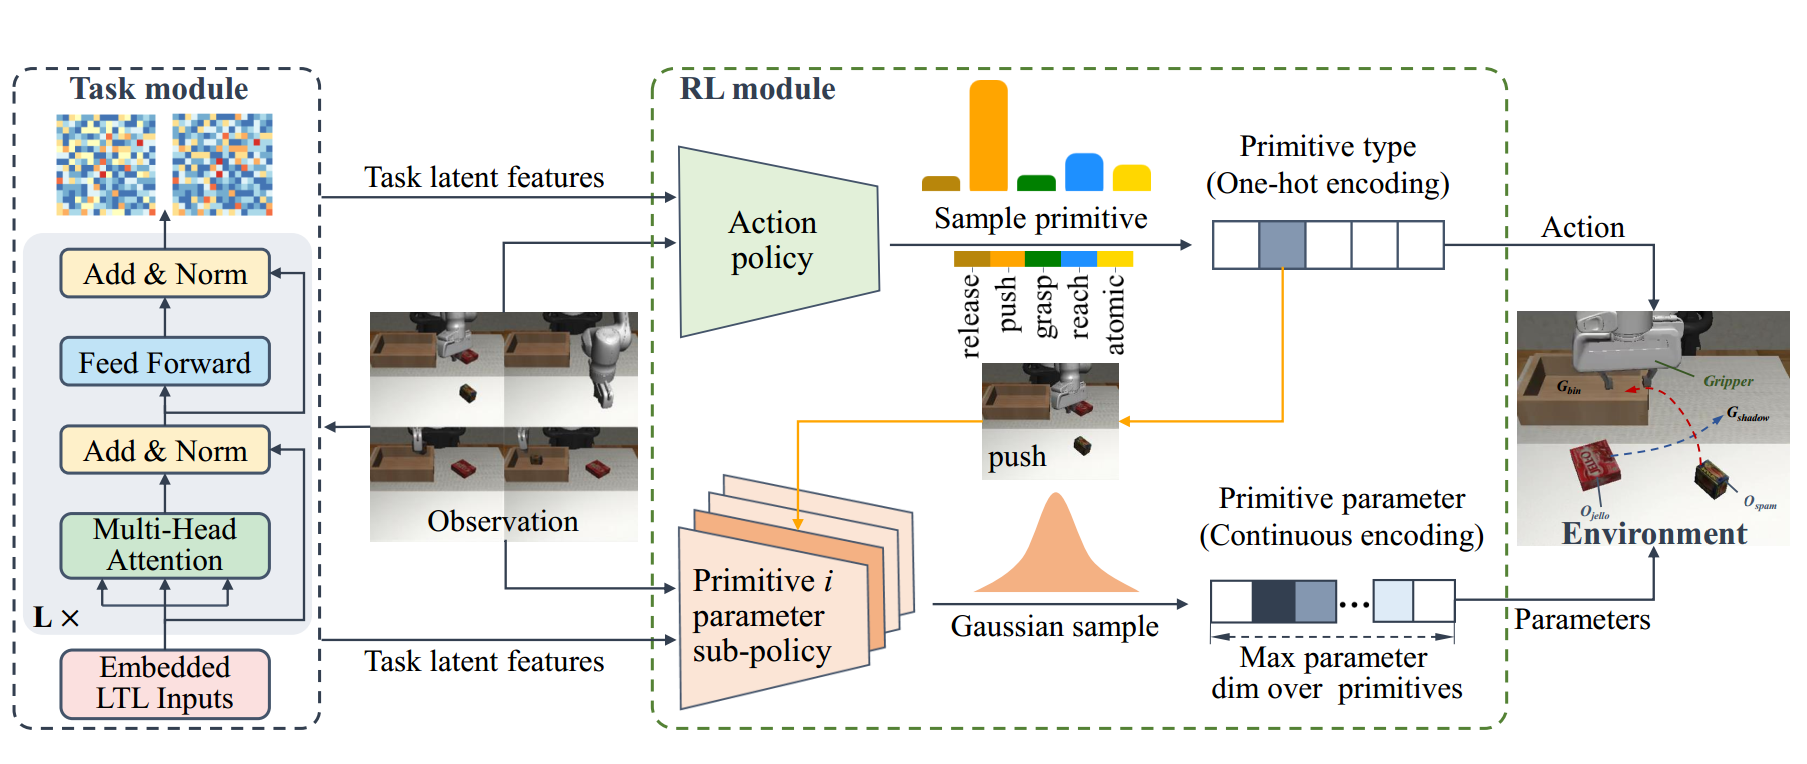
Paper IEEE Transactions on Cybernetics (Journal), 2023, Accepted We develop Task-driven Reinforcement learning with Action Primitives (TRAPs), a new manipulation skill learning framework that augments standard reinforcement learning algorithms with formal methods and parameterized action space. |
|
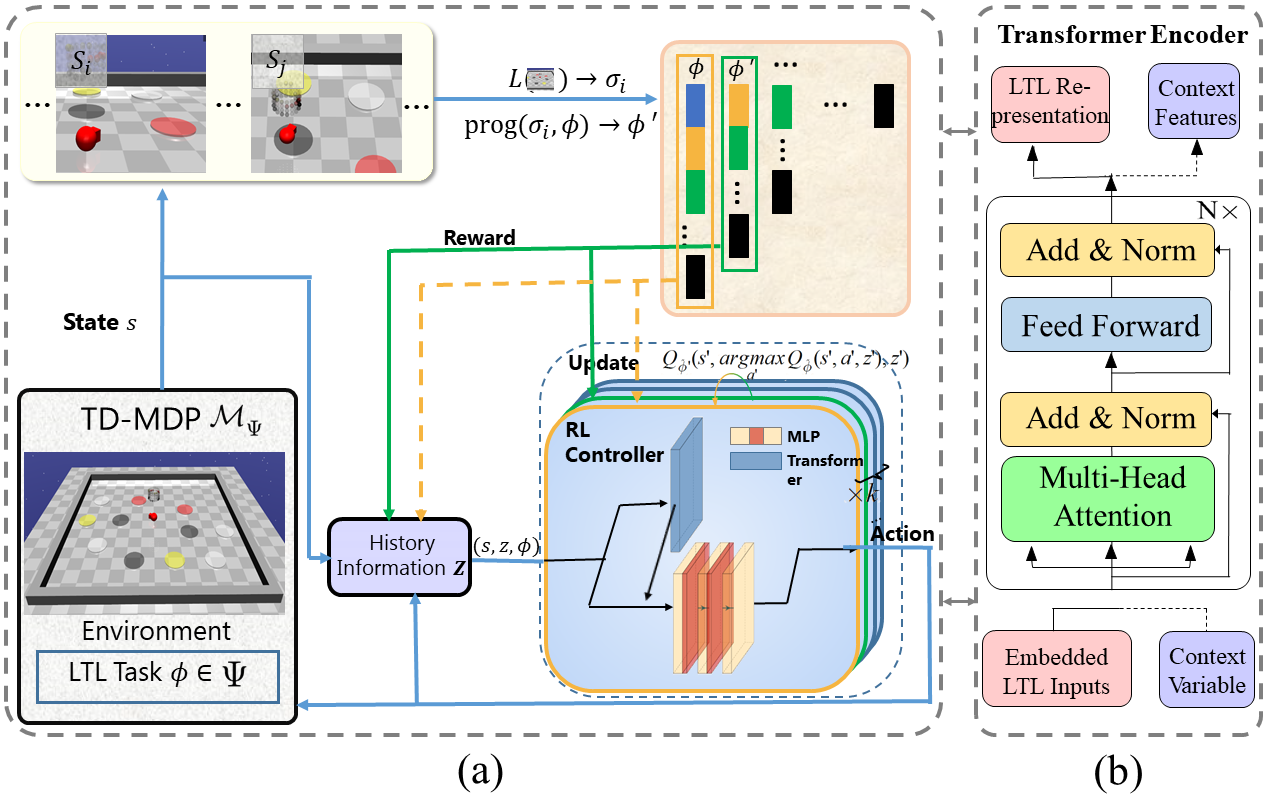
Paper / Code IEEE RA-L (Journal), 2023, Accepted We develop a Double-Transformer-guided Temporal Logic framework (T2TL) that exploits the structural feature of Transformer twice. |
|
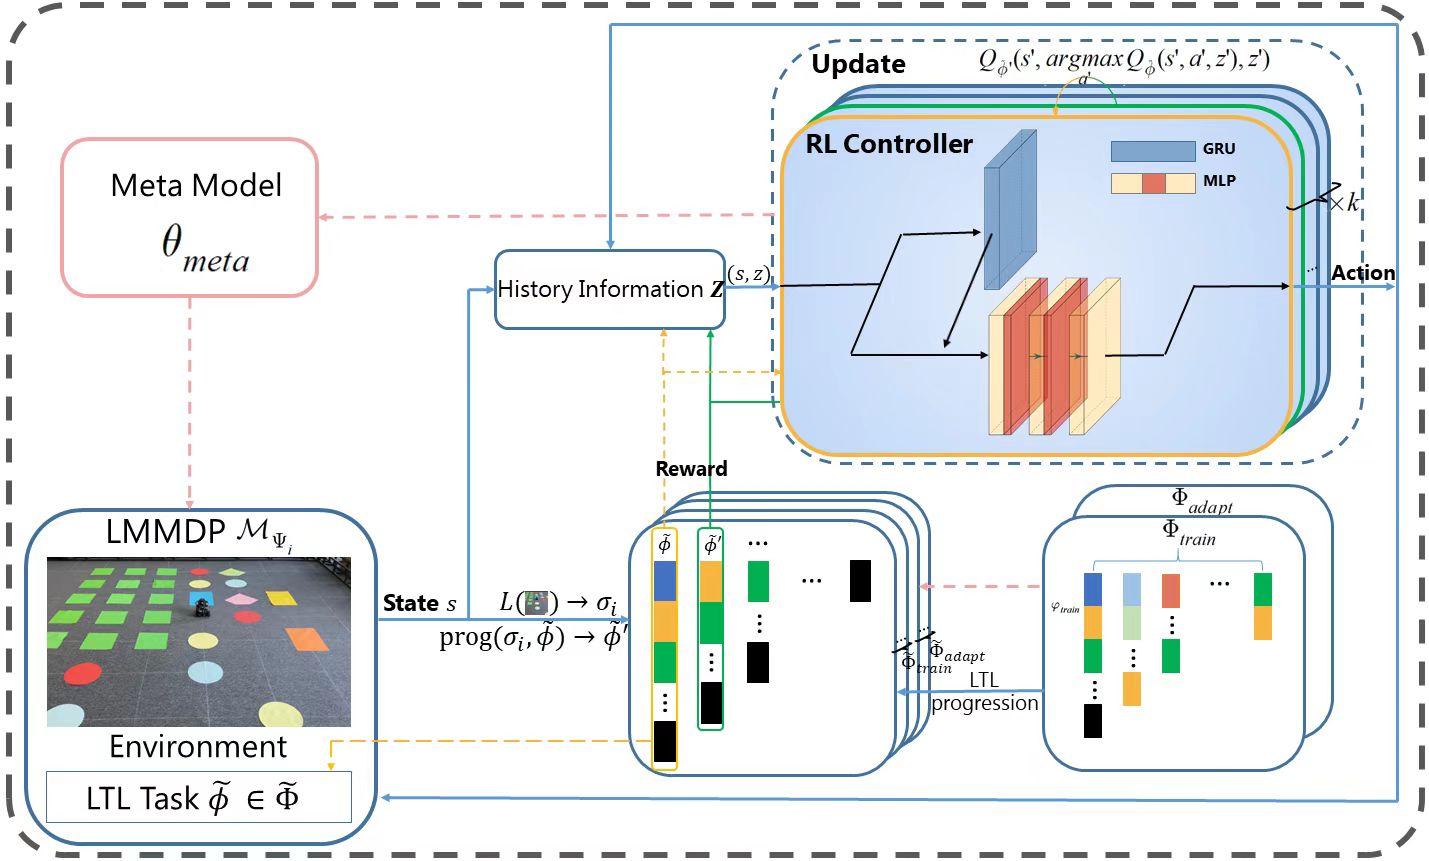
Paper IEEE RA-L (Journal), 2022, Accepted We develop a meta Q-learning of multi-task (MQMT) framework where the robot effectively learns a meta model from a diverse set of training tasks and then generalizes the learned model to a new set of tasks. |
|
This template is a modification to Jon Barron's website. |